96GB Blackwell: SGLang NVFP4 + DFlash2 vs vLLM BF16, Measured
Measured Qwen3.8-27B serving on one 96GB Blackwell GPU: a BF16 vLLM baseline, an NVFP4 SGLang lane, and the throughput and latency that decide which holds.
Filed under Local LLM Inference· see every report on this topic
On one RTX PRO 6000 Blackwell 96GB, keep a BF16 vLLM baseline. Use the NVFP4 SGLang lane only after its client contract and thermal limit pass: it reached 141.49 output tok/s, retrieved from 261,494 prompt tokens, and peaked at 91°C.
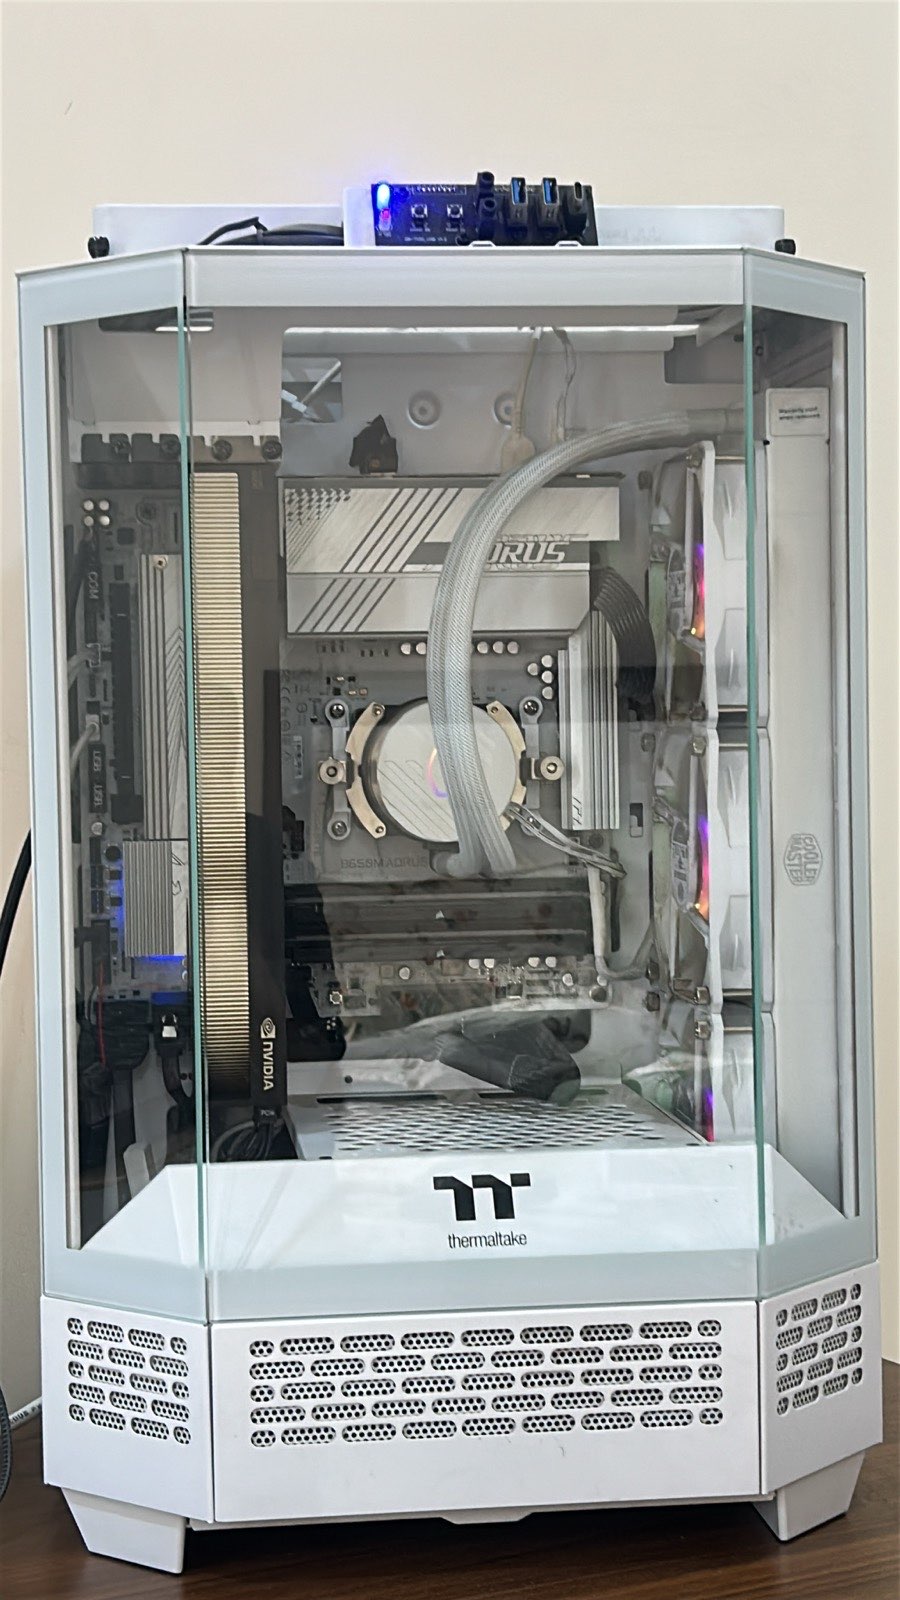
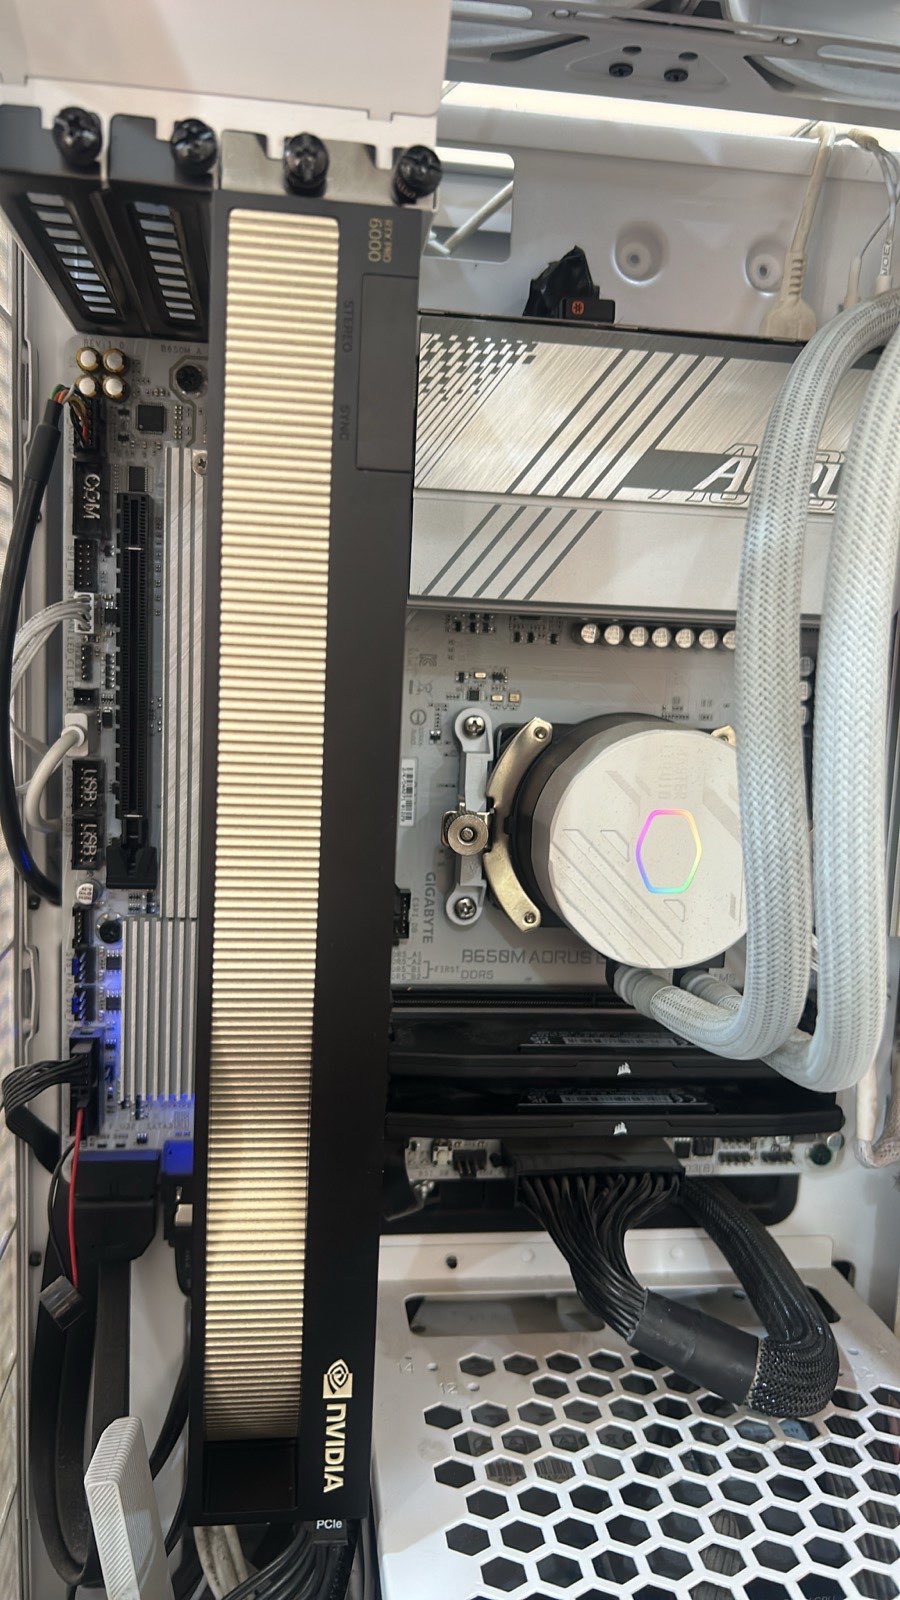
This 21 August 2026 cutover ran Qwen3.8-27B on one RTX PRO 6000 Blackwell Max-Q with 96GB VRAM and about 60GB host RAM.
1. Scope
This guide covers one machine and one cutover: Qwen3.8-27B on a single RTX PRO 6000 Blackwell Max-Q (96GB VRAM, ~60GB host RAM), run on 21 August 2026. It compares a vLLM 0.24 BF16 baseline against an SGLang NVFP4 lane with DFlash2 speculative decoding, with measured throughput, latency, VRAM, and thermal numbers for each. Read it before you plan a local lane on a 96GB Blackwell card; skip it if your target is multi-GPU or sub-30GB hardware.
2. What 96GB buys on Qwen3.8-27B
Qwen3.8-27B has 64 layers: 16 groups of three Gated DeltaNet linear-attention layers and one Gated Attention layer. Its 262,144-token native context also needs KV, recurrent state, CUDA graphs, and workspace.
| Item | Measured / reported |
|---|---|
| GPU VRAM | 97,887 MiB visible (“96GB”) |
| BF16 Qwen3.8-27B checkpoint on disk | 51.77 GiB |
| vLLM BF16 lane at 262K | 445,568 GPU-KV tokens; ~90.7 GiB VRAM after init |
| SGLang NVFP4 lane at startup | Target 20.14 GB + draft 3.72 GB; ~86.3 GB VRAM; 590,058 KV-token capacity |
At 262K, BF16 left about 14 GiB host RAM with swap disabled. A projected 524K BF16-KV lane was about 88 GiB and remains unverified.
3. Keep a baseline, then add a capacity lane
The vLLM 0.24 BF16 baseline used --max-model-len 262144, BF16 KV, chunked prefill, prefix caching, 32 GiB CPU KV offload, qwen3, qwen3_coder, and three-token MTP. Needle retrieval took 43.07s at 128K and 115.31s at 250K. SGLang dev kept port 8000 and alias qwen3.8-27b with an NVFP4 target and DFlash2 draft.
sglang serve --trust-remote-code \
  --model-path RadixArk/Qwen3.8-27B-NVFP4 \
  --served-model-name qwen3.8-27b \
  --kv-cache-dtype bfloat16 --mem-fraction-static 0.85 \
  --max-running-requests 4 --max-mamba-cache-size 20 \
  --attention-backend flashinfer --chunked-prefill-size 2048 \
  --reasoning-parser qwen3 --tool-call-parser qwen3_coder \
  --speculative-algorithm DFLASH \
  --speculative-draft-model-path z-lab/Qwen3.8-27B-DFlash2 \
  --speculative-num-draft-tokens 8 \
  --mamba-radix-cache-strategy extra_buffer --mamba-ssm-dtype float32
DFlash2 was the difficult part. Engine, NVFP4 weights, draft model, and scheduler changed, so results describe the lane. Setup took longer than expected. If you’re replicating this, budget for it. It paid off: before this lane I was on vLLM with MTP, and MTP was not working well on this card. SGLang says gains vary by model, hardware, and configuration in its speculative-decoding documentation.
4. Lane comparison: choose by the work
My take: keep vLLM as the BF16 comparison point; use SGLang for the smaller footprint and aggregate output, but only after the smoke and thermal checks pass.
| Lane | Config | VRAM after init | Measured throughput |
|---|---|---|---|
| vLLM baseline | vLLM 0.24, BF16, 262K | ~90.7 GiB | Not measured |
| SGLang capacity | Dev, NVFP4 + DFlash2, c4 | ~86.3 GiB | 141.49 serial; 408.62 c4 tok/s |
Latency and context checks: vLLM 128K in 43.07s, 250K in 115.31s (short-output throughput and TTFT were not collected). SGLang median TTFT 44.6 ms; 261,494-token retrieval in 99.95s.
The smoke suite returned the alias, correct non-thinking content, and reasoning_content with 60 reasoning tokens. It accepted chat_template_kwargs and correct tool_calls. /version was absent; /metrics returned 404 because metrics were disabled.
The 21 August artifact used 1,024-token outputs unless noted:
| Workload | Observed | What it establishes |
|---|---|---|
| Serial, 1,024-token output | 141.49 tok/s median end-to-end; 44.6 ms median TTFT | Short-prompt sustained decode |
| Concurrency 2 | 281.31 aggregate tok/s; p50 TTFT 204.7 ms | Aggregate throughput at c2 |
| Concurrency 4 | 408.62 aggregate tok/s; p50 TTFT 83.8 ms | Aggregate throughput at configured cap |
| Full native context | 261,494 prompt tokens (99.75% of 262,144); TTFT 99.95 s; needle correct | Native-limit prefill and retrieval |
DFlash acceptance ranged 0.22–0.74 across workloads, with mean accepted draft length 2.5–6.2 tokens. Across 137 one-second samples, utilization averaged 98.26%, temperature 85.89°C, and peaks were 91°C and 327.61 W. Do not expand load at 90°C without changing cooling, power, or concurrency.
What we have not measured: randomly timed 100K-token agent workloads or the concurrency point where performance falls off. The c2 and c4 results do not establish either.
5. Failures worth testing before cutover
| Symptom | Cause | Narrow fix |
|---|---|---|
FP8 candidate dies at startup: DeepGEMM … Unknown recipe |
vLLM 0.24.0 SM120 kernel regression (issue #47130) | Isolate its image; scope VLLM_USE_DEEP_GEMM=0; leave BF16 unchanged |
| Thinking missing after engine swap | Client reads only reasoning or reasoning_content |
Use an accessor for both; rerun smoke suite |
Empty content, finish_reason=length |
Thinking spent the output budget | Raise output cap or set enable_thinking: false |
| Long-context rerun gets faster | Prefix/radix cache is warm | Report cold prefill and warm reuse separately |
| DFlash + Qwen NVFP4 prefill-graph crash on other Blackwell cards | Reported RTX 5090 failure (SGLang issue #35437); not reproduced here | Pin the image digest and treat as third-party risk |
| GPU reaches 91°C under saturation | Cooling envelope exceeded | Stop load growth; change cooling, power, or concurrency |
| New lane cannot start; GPU remains full | Orphaned vLLM workers hold VRAM | Stop scoped unit; verify VRAM and port release |
Bottom line
Choose BF16 vLLM as a debugging baseline. Choose NVFP4 SGLang when 141.49 serial or 408.62 c4 tok/s fits and its contract and thermal gate pass. Its correct 261,494-token retrieval still took 99.95s to first token and peaked at 91°C.
Sources
- Qwen3.8-27B model card, hybrid DeltaNet layout, 262,144 native context, MTP, YaRN guidance (fetched 21 Aug 2026)
- SGLang speculative-decoding docs, DFlash configuration and tuning (fetched 21 Aug 2026)
- vLLM issue #47130, SM120/DeepGEMM FP8 warmup regression and scoped workaround (verified live)
- SGLang issue #35437, third-party DFlash prefill-graph failure report (verified live)
- Observed artifacts: benchmark JSON, API smoke JSON, and 137-row GPU sample CSV from the 21 August 2026 run; vLLM BF16 deployment reports of 18 August 2026.
Related posts
vLLM MTP: Faster Inference That Quietly Broke Tool Calls
Multi-token prediction cut our latency, then quietly corrupted tool calls. What MTP does, how the failure presented, and the settings that made it safe again.
LLM Fine-Tuning: Your Dataset Is the Hard Part, Not the Run
For an internal smart-contract audit SFT lane, hold the run until the dataset passes dedup, leakage, grounding, negative-coverage, and truncation gates.
Self-Hosted LTX 2.3: Failure Modes and Trade-Offs
Receipt-backed LTX 2.3 and ComfyUI workflows show the GPU, retry, and failure-mode trade-offs behind self-hosting versus an occasional hosted API call.
Get the next verdict before it's everywhere.
One email when a new lab post or cost table ships. No spam, no confirmation step — unsubscribe anytime.